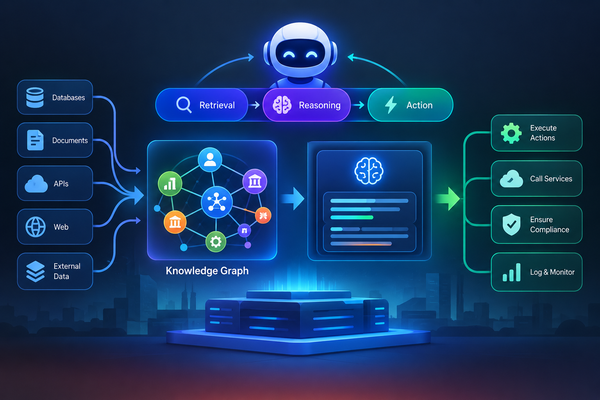
AI & Automation Presentation: From Retrieval to Reasoning: Building Production-Ready Agentic AI Systems with Knowledge Graphs Expert-level deep dive: Presentation: From Retrieval to Reasoning: Building Production-Ready Agentic AI Systems with Knowledge Graphs
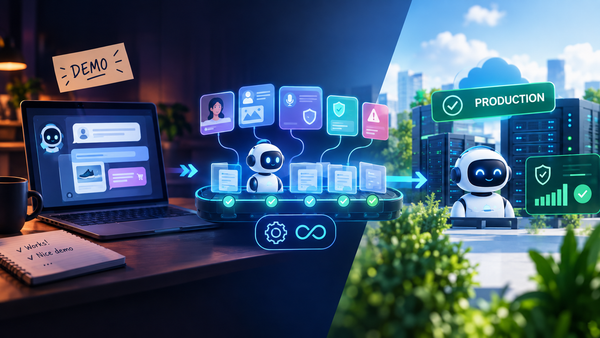
AI & Automation Presentation: From AI Agent Demo to Production: Automated Testing and Evaluation Expert-level deep dive: Presentation: From AI Agent Demo to Production: Automated Testing and Evaluation
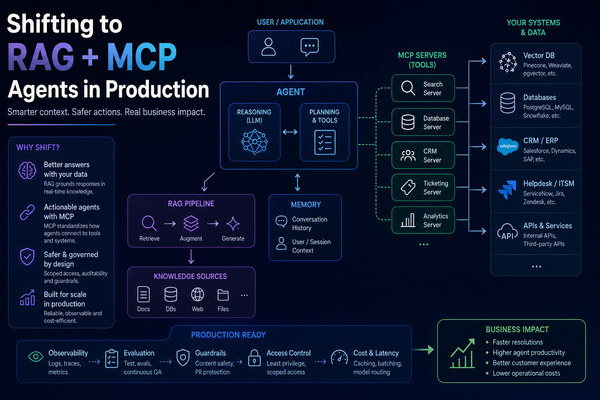
AI & Automation Shifting to RAG + MCP Agents in Production RAG + MCP agents combine knowledge retrieval with live tool actions, and they are increasingly common in production AI systems. But shipping one to production surfaces failure modes that never show up in a demo. This article walks through five concrete failures documented by Sudip P. after deploying a RAG + MCP
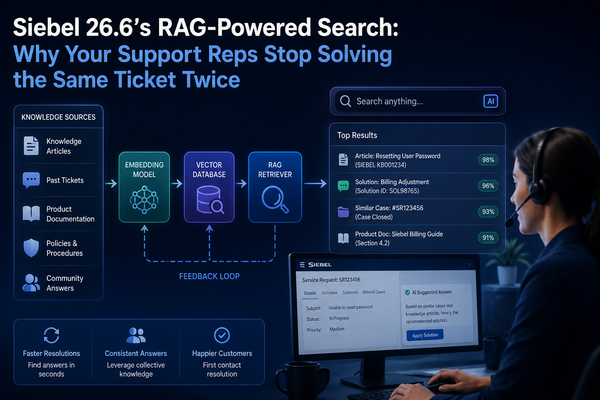
AI & Automation Siebel 26.6’s RAG-Powered Search: Why Your Support Reps Stop Solving the Same Ticket Twice Expert-level deep dive: Siebel 26.6’s RAG-Powered Search: Why Your Support Reps Stop Solving the Same Ticket Twice
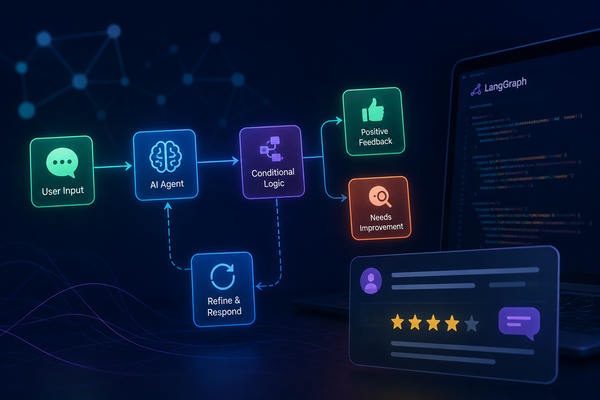
AI & Automation Building Intelligent Feedback Systems: A Deep Dive into Conditional Agentic Workflows with LangGraph The field of artificial intelligence has witnessed tremendous growth in recent years, with AI-powered systems being increasingly adopted across various industries. However, the development of intelligent feedback systems that can learn from their environment and adapt to changing conditions remains a significant challenge. As AI systems become more pervasive, the
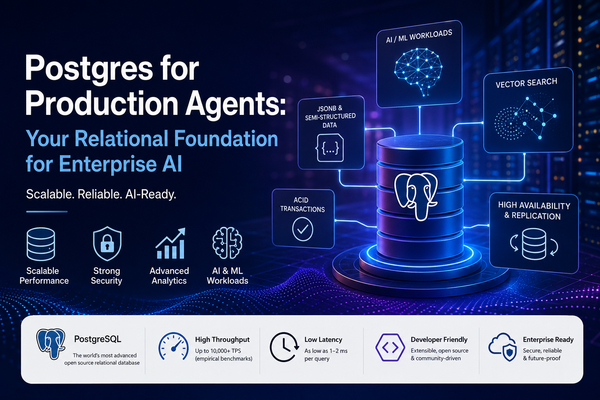
AI & Automation Postgres for Production Agents: Your Relational Foundation for Enterprise AI Most teams building AI agents reach for a vector database as their first infrastructure decision. Gwen Shapira, co-founder and CPO of Nile, argues that is often the wrong first move: Postgres, a database most teams already run, already does most of what an agent needs, if you know which parts
AI & Automation GPU-Resident Top-K for Agentic RAG: I Built a CUDA Kernel So My Retrieval Step Would Stop Bouncing Off the GPU Expert-level deep dive: GPU-Resident Top-K for Agentic RAG: I Built a CUDA Kernel So My Retrieval Step Would Stop Bouncing Off the GPU
AI & Automation LangChain Explained: Models, Prompts, Chains, Memory, Indexes and Agents Expert-level deep dive: LangChain Explained: Understanding Models, Prompts, Chains, Memory, Indexes, and Agents
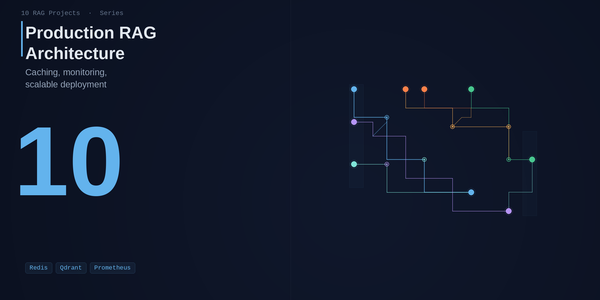
RAG 10. Production RAG - Everything Together Nine articles, nine patterns. Now build the service that ships: Pydantic config, request-ID middleware, async document ingestion, a unified multi-mode query endpoint, K8s health probes, and a multi-stage Dockerfile.
RAG 9. RAG with Structured Outputs - JSON Mode + Pydantic Force your RAG pipeline to always return valid, typed data. Combine OpenAI JSON mode, Pydantic v2 schemas, and LangChain output parsers to build a pipeline where every response is schema-validated.
RAG 8. Corrective RAG (CRAG) - Self-Correcting Retrieval Implement CRAG: a retrieval pipeline that grades its own results and automatically corrects poor retrievals before generating. Combines LangGraph state machines with a web search fallback.
RAG 7. Agentic RAG - ReAct Agent with Tool-Calling Give your RAG system the ability to reason, act, and self-correct. Build a ReAct agent that decides when to retrieve, when to search the web, and when to compute — using LangGraph and custom tools.
RAG 6. GraphRAG - Multi-Hop Reasoning with a Local Knowledge Graph Go beyond flat vector search. Build a knowledge graph from your documents, run multi-hop queries that traverse entity relationships, and combine graph traversal with vector retrieval for richer answers.
RAG 5. Evaluating RAG Quality with RAGAS Stop guessing whether your RAG pipeline is good. Use RAGAS to measure faithfulness, answer relevancy, context precision and recall — and learn to interpret the metrics to drive concrete improvements.
RAG 4. Streaming RAG Chat - FastAPI SSE + React Add token-by-token streaming to your RAG pipeline. Server-Sent Events from FastAPI, a React client with AbortController, and the nuances of streaming structured retrieval responses.
RAG 3. Multi-Tenant Document Q&A API Build a multi-tenant RAG API where each tenant's documents are fully isolated. FastAPI, per-tenant ChromaDB collections, JWT authentication, and a clean REST interface for document ingestion and querying.
RAG 2. Build Your First RAG System from Scratch Strip away every framework and build RAG with raw Python — numpy cosine similarity, direct OpenAI calls, no LangChain. Understand exactly what the abstractions hide before you use them.
RAG 1. Document Analysis with LLMs Build a production-ready document Q&A pipeline from scratch. Load PDFs, Word files and web pages, split them into semantic chunks, embed with open-source models, store in a vector DB, and answer questions with full source attribution — zero paid APIs required.
AI & Automation Your AI Agent Works Perfectly in the Demo. Here Are the 6 Ways It Dies in Production with AI Automation AI agents rarely fail in demos - they fail in production. Discover the 6 critical reasons AI automation systems break at scale: model drift, weak governance, poor observability, data quality issues, scalability bottlenecks, and security gaps.
AI & Automation Deploying a Multistage Multimodal Recommender System on Amazon Elastic Kubernetes Service Deploy a scalable multistage multimodal recommender system on Amazon Web Services using Amazon Elastic Kubernetes Service. Optimize inference pipelines, autoscaling, and GPU workloads for high-performance personalized recommendations.
AI & Automation OpenAI Introduces Websocket-Based Execution Mode to Reduce Latency in Agentic Workflows OpenAI has introduced a WebSocket-based execution mode designed to reduce latency in agentic AI workflows by enabling faster, persistent bidirectional communication between agents and execution environments.
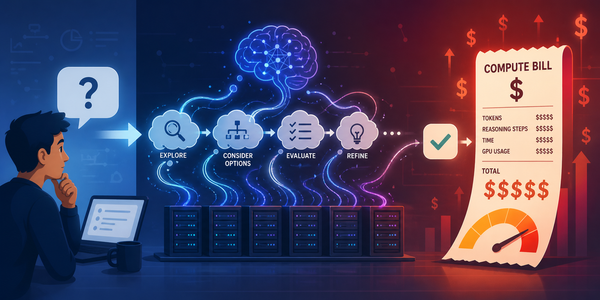
AI & Automation Inference Scaling (Test-Time Compute): Why Reasoning Models Raise Your Compute Bill Reasoning models use more compute at inference time by exploring multiple paths, evaluating options, and refining outputs. This increases token usage, latency, and overall cost compared to standard single-pass models.
AI & Automation Mistral AI Introduces Workflows for Orchestrating Enterprise AI Processes Your AI models are capable. Your production deployments are not. Mistral's Workflows addresses the infrastructure gap that kills every enterprise AI pilot — built on the same durable execution engine trusted by Netflix, Stripe, and Salesforce.
AI & Automation Designing Cognitive Memory for AI Agents AI agents fail at continuity due to stateless design. LinkedIn’s Cognitive Memory Agent (CMA) introduces persistent, structured memory—episodic, semantic, procedural - enabling agents to retain context, adapt over time, and move from prompt-driven responses to truly stateful intelligence.
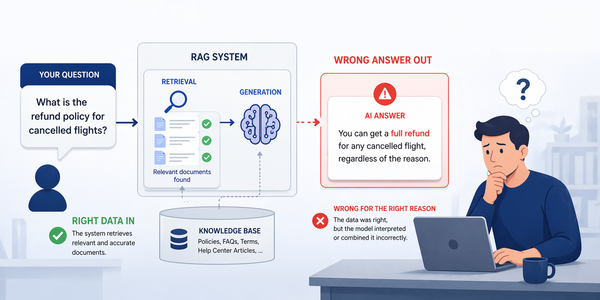
AI & Automation The Hidden Failure Mode of RAG Systems: Right Data, Wrong Answer Your RAG retrieves the right documents - then hallucinates anyway. The culprit isn't the model or the retriever. It's conflicting context entering the generator undetected. Here's the architectural fix five research groups converged on in 2025–2026.